
01The Verification Gap in Production
Deploying an LLM behind an API requires operating on blind trust. We assume the provider runs the exact model version requested. For low-stakes applications, this is acceptable. If a router swaps a model for a distilled version to save cost or latency, the impact remains negligible.
For legal, medical, or financial workflows, blind trust is a liability. When a model generates a hallucination or an incorrect calculation, engineers must identify the exact weights that produced that output. Currently, cryptographic proof that a response came from a claimed model does not exist. Systems rely on provider logging and infrastructure assumptions.
02Compute Overhead of Cryptographic Proofs
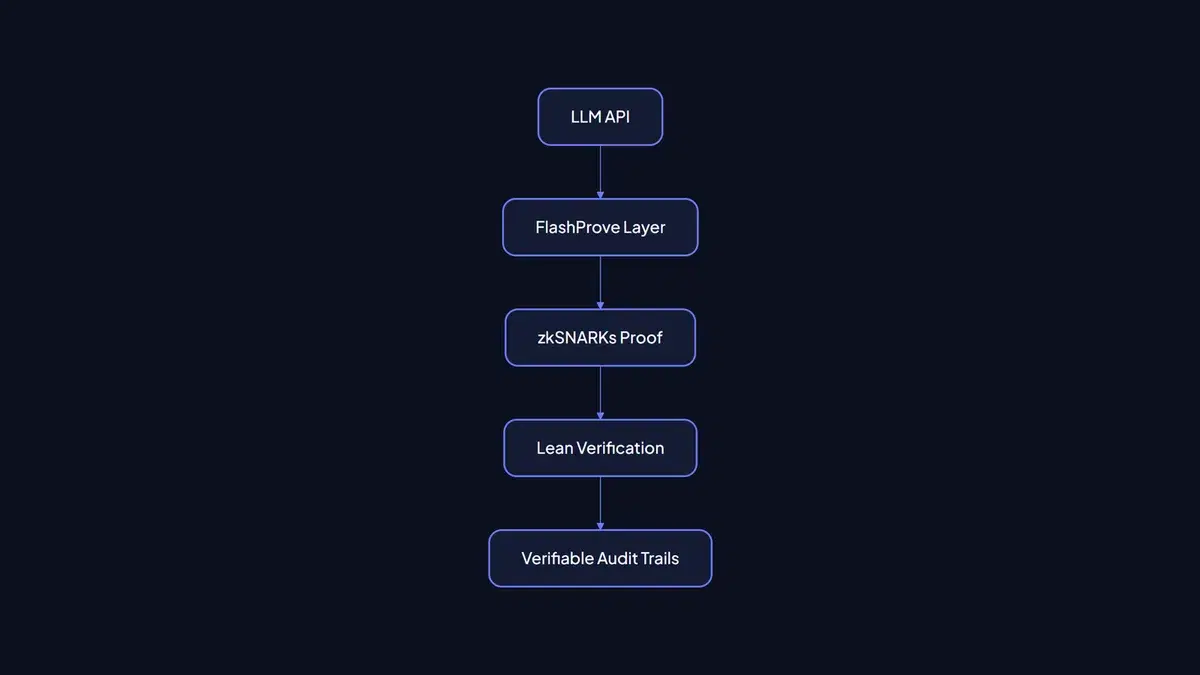
FlashProve demonstrates that zkSNARKs can generate a cryptographic proof verifying a specific model produced a specific token sequence.
Generating proofs for a 400B-parameter mixture of experts model at 110 tokens per second on an H100 requires significant engineering. This introduces a 70x to 95x increase in GPU time compared to standard inference on vLLM.
For high-velocity product teams, this overhead breaks general chat interfaces. For batch processing or sensitive document analysis where model identity drives compliance, the math changes. This shifts the use case from real-time chat to verifiable batch audit trails.
03Formal Verification with Lean
The research utilizes Lean for formal verification. Traditional unit tests struggle with the non-deterministic nature of LLM pipelines. Top-level auditable statements in Lean replace probabilistic checking with mathematical certainty regarding security guarantees.
Systems requiring legal model provenance must first evaluate whether inference pipelines tolerate a 100x latency penalty. If not, architectures must split. Standard inference handles low-stakes tasks, while verifiable pipelines process audit-required tasks.
04Production Constraints
FlashProve hides model weights to protect proprietary providers, but it exposes the architecture.
These tools remain at the research stage. Integrating a fast C++ verifier and a Lean verifier into a production CI/CD pipeline requires building dedicated monitoring, scaling, and failure handling for a cryptographic layer running two orders of magnitude slower than the base model.
05Sources
- Progress on provable inference for large language models (anthropic.com)
- [Discussion: Progress on provable inference for large language models](https://news.ycombinator.com/item?id=50368626) (Hacker News)